Separate
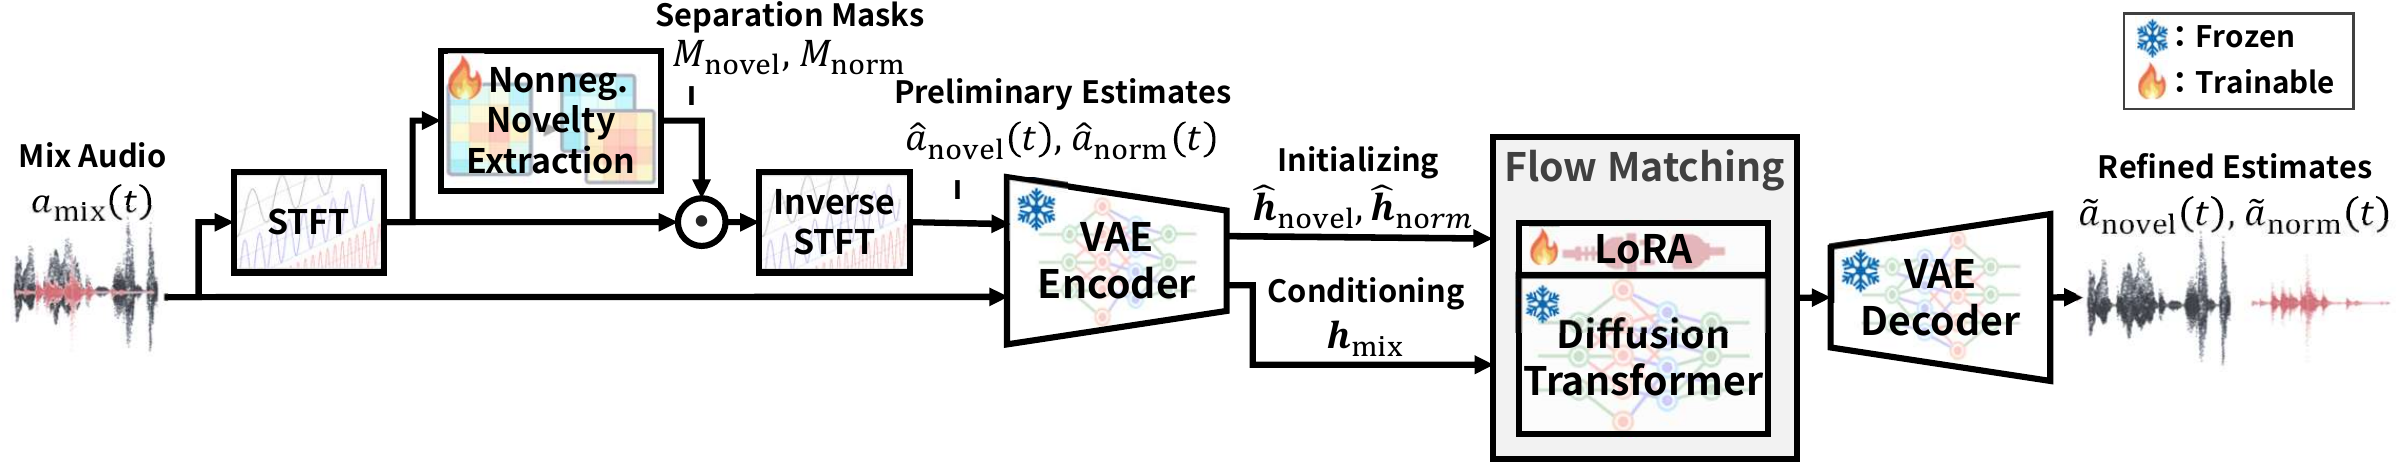
Nonnegative Novelty Extraction (NNE) estimates normal and novel components using a dictionary learned from normal recordings.
The University of Tokyo
The idea
A novelty score flags a departure from everyday sounds. NovelSep also produces an audio waveform that lets a listener inspect the evidence behind that score. A novel sound is new relative to an environment’s normal sound distribution; novelty does not necessarily indicate danger.
Nonnegative Novelty Extraction (NNE) estimates normal and novel components using a dictionary learned from normal recordings.
Flow matching in a pretrained audio latent space refines the initial estimates. Normal Region Exclusion selects surrogate novel audio for adaptation.
The energy of the refined novel component provides a novelty score. The same component can be played back as a listenable explanation.
Listening room
Compare four methods on five novel-containing mixtures and five normal-only recordings. All method outputs below are estimates of the novel component.
Start with the mixture and references. Then compare the estimated novel sounds. Successful separation preserves the novel event and suppresses the normal background. A normal-only example should produce a quiet novel estimate.
CLAP is audio embedding cosine similarity to the novel reference; SAJ is the automated SAM Audio Judge overall score. Higher is better for both. Scores are undefined for silent normal-only novel references and are shown as N/A.
Loading listening examples…
Consistent playback. No track is normalized independently. A shared attenuation, when needed, keeps every track within an example below full scale and preserves relative amplitudes. Keep the player volume unchanged when comparing methods.
Spectrogram levels are relative to the maximum magnitude across all reference and estimated tracks in the selected example. Detection labels are the saved predictions from each method’s tuning-selected threshold.
Use NovelSep
The release provides reusable NovelSep and Normal Region Exclusion classes, scene-specific model weights, and reproducible demo selection.
Original source code is available for noncommercial research only. See the LICENSE.